In today’s digital world, managing the flow of data and requests between clients and servers is critical for maintaining the performance, security, and availability of web services. One key technique used to achieve this is rate limiting. This blog will delve into the concept of rate limiting, its importance, methods, and best practices.
Table of Contents
What is Rate Limiting?
Rate limiting controls the amount of incoming and outgoing traffic to or from a network. Essentially, it limits how many requests a user can make to a server within a specific time frame. This is crucial for preventing abuse, ensuring fair usage, and maintaining the stability and performance of the server.
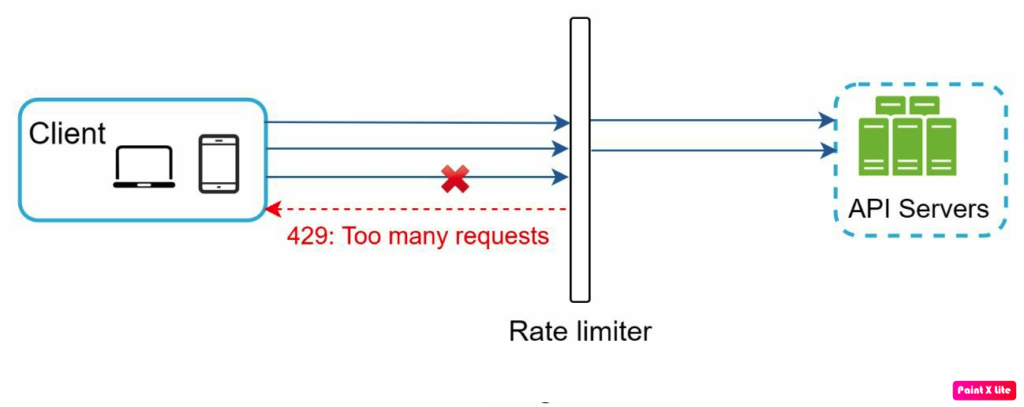
Image source: System Design Interview — An insider’s Guide by Alex Xu
Advantages of Rate Limiting
- Prevents Abuse and DDoS Attacks: Rate limiting helps mitigate denial-of-service (DoS) and distributed denial-of-service (DDoS) attacks by limiting the number of requests an attacker can make. This protection ensures that malicious users cannot overwhelm your server with excessive requests, keeping your services available to legitimate users.
- Ensures Fair Usage: By controlling the request rate, rate limiting ensures that no single user can monopolise server resources. This fairness is particularly important in multi-tenant environments, where resources are shared among many users.
- Improves System Performance and Stability: Rate limiting can prevent server overload, which can lead to crashes or degraded performance. By capping the number of requests, you can ensure that your system remains responsive and stable, providing a better user experience.
- Cost Management: In cloud-based environments, resources such as bandwidth, CPU, and memory are often billed based on usage. Rate limiting helps control these costs by preventing excessive use, thus avoiding unexpected expenses.
- Enhances Security: Rate limiting can protect against brute force attacks on login pages or APIs by restricting the number of attempts a user can make. This security measure reduces the risk of unauthorised access.
- Data Integrity: By controlling the rate of write operations, rate limiting helps maintain data integrity, especially in databases. It prevents scenarios where rapid, uncontrolled writes could lead to data corruption or inconsistent states.
How Does Rate Limiting Work?
Rate limiting can be implemented in various ways, depending on the needs and infrastructure of the system. Here are some common methods:
- Token Bucket
- Leaky Bucket
- Fixed window counter
- Sliding window logs
- Sliding window counter
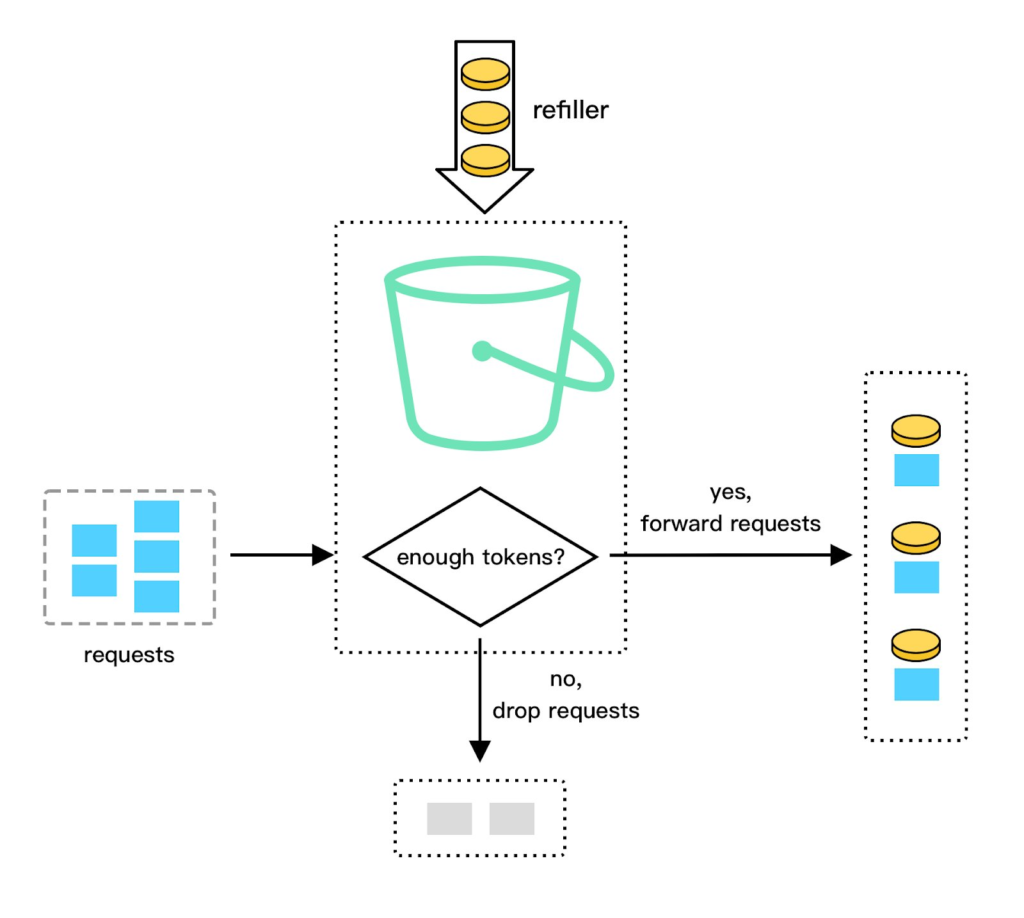
Token bucket algorithm
- A bucket holds tokens, each representing the right to make a request.
- Tokens are added to the bucket at a fixed rate.
- Each incoming request consumes a token.
- The request is denied if the bucket is empty until more tokens are available.
Leaky bucket algorithm
The leaky bucket algorithm is similar to the token bucket except that requests are processed at a fixed rate. It is usually implemented with a first-in, first-out (FIFO) queue. The algorithm works as follows:
- When a request arrives, the system checks if the queue is full. If it is not full, the request is added to the queue.
- Otherwise, the request is dropped.
- Requests are pulled from the queue and processed at regular intervals.

Fixed window counter algorithm
The fixed window counter algorithm works as follows:
- The algorithm divides the timeline into fixed-sized time windows and assigns a counter for each window.
- Each request increments the counter by one.
- Once the counter reaches the predefined threshold, new requests are dropped until a new time window starts.
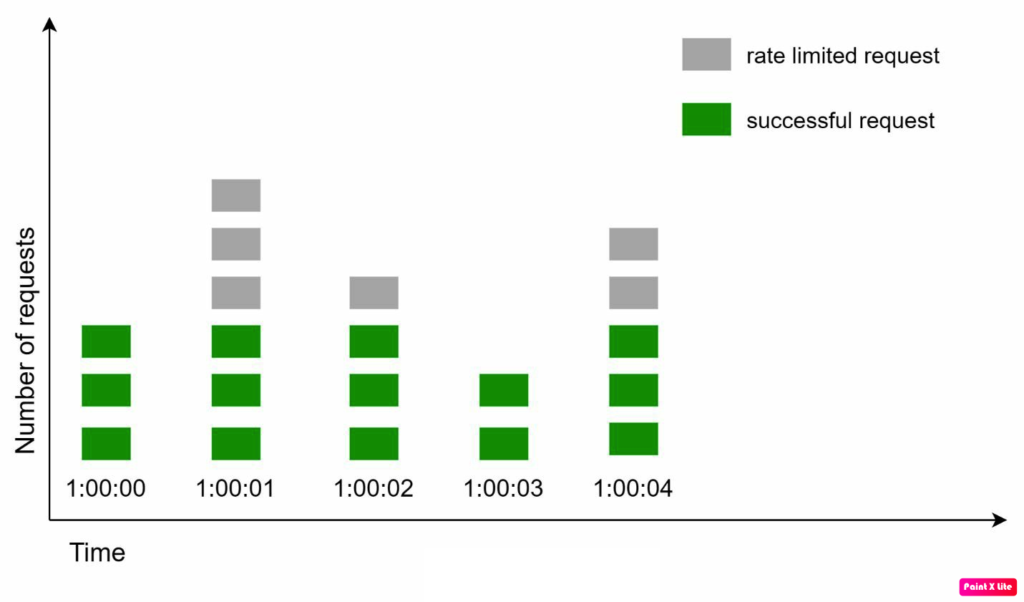
- A major problem with this algorithm is that a burst of traffic at the edges of time windows could cause more requests than the allowed quota.
- For example, if the window size is 1 minute and the limit is 100 requests per minute, it is possible to send 100 requests at the very end of one window and another 100 requests at the very beginning of the next window, resulting in 200 requests in a very short time.
Sliding window log algorithm
The fixed window counter algorithm has a major issue: it allows more requests to go through at the edges of a window. The sliding window log algorithm fixes the issue. It works as follows:
Instead of counting requests per fixed time bucket, you store a log of timestamps for every request. When a new request arrives, you:
- Remove all timestamps older than
now - window_size - Count what remains
- If count < limit → allow and log the timestamp
- If count >= limit → reject
Timestamp data is usually kept in a cache, such as a sorted sets of Redis.

In this example, the rate limiter allows 2 requests per minute. Usually, Linux timestamps are stored in the log. However, a human-readable representation of time is used in our example for better readability.
- The log is empty when a new request arrives at 1:00:01. Thus, the request is allowed.
- A new request arrives at 1:00:30; the timestamp 1:00:30 is inserted into the log. After the insertion, the log size is 2, not larger than the allowed count. Thus, the request is allowed.
- A new request arrives at 1:00:50, and the timestamp is inserted into the log. After the insertion, the log size is 3, larger than the allowed size of 2. Therefore, this request is rejected even though the timestamp remains in the log.
- A new request arrives at 1:01:40. Requests in the range [1:00:40,1:01:40) are within the latest time frame, but requests sent before 1:00:40 are outdated.
- Two outdated timestamps, 1:00:01 and 1:00:30, are removed from the log. After the removal operation, the log size becomes 2; therefore, the request is accepted.
Note:
- Rate limiting implemented by this algorithm is very accurate. In any rolling window, requests will not exceed the rate limit.
- The algorithm consumes a lot of memory because even if a request is rejected, its timestamp might still be stored in memory.
Sliding window counter algorithm
The Sliding Window Counter algorithm is a hybrid approach that combines elements of both the Fixed Window(cheap, memory-efficient) and Sliding Window Log(precise, memory-heavy) algorithms. It aims to provide a more balanced and efficient rate-limiting mechanism by using counters that are updated based on the sliding window concept.
A sliding window counter is similar to a fixed window counter, but it smooths out bursts of traffic by adding a weighted count in the previous window to the count in the current window.
Core Idea
Keep two fixed-window buckets: the current window and the previous window. When a request arrives, estimate how many requests fall inside the true sliding window using a weighted blend of both buckets.
estimated_count = prev_count × (1 - elapsed_fraction) + curr_countWhere elapsed_fraction = how far you are into the current window.
Example Window size: 10s, limit: 10 requests
Previous window [0–10s]: 8 requests
Current window  [10–20s]: 3 requests
Request arrives at t=14s → elapsed_fraction = 4/10 = 0.4

estimated = 8 × (1 - 0.4) + 3
          = 8 × 0.6 + 3
          = 4.8 + 3
= 7.8 → below 10 → allowThe intuition: you assume the 8 previous requests were uniformly distributed, so roughly 60% of them (the part overlapping your current sliding window) still count.
Example 2

- Suppose the limit is 4 requests/minute in the above diagram.
- There are 4 requests in the window [1:00:00, 1:01:00) and 2 requests in the window [1:01:00, 1:02:00).
- For 2 requests that arrive at 1:01:15, which is at the 25% position of the window [1:01:00, 1:02:00), we calculate the request count by the formula: 3 x (1 – 25%) + 2 = 4.25 > 4. Thus, we reject this request.
- Even though both windows don’t exceed the limit, the request is rejected because the weighted sum of the previous and current windows does exceed the limit.
- In other words, in the window [1:00:15, 1:01:15], we have 5 requests; thus, we have to reject this request.
Pros:
- It is more efficient than Sliding Window Log as it avoids storing individual timestamps.
- Provides a good approximation of the sliding window behaviour.
- Reduces memory usage compared to storing logs.
Cons:
- Less precise than the Sliding Window Log.
- Requires careful tuning of sub-window size.
Why the Approximation Works
The worst-case error is about 1–2% of your limit in practice. The only scenario where it’s meaningfully wrong is if all previous requests clustered at the very end of the prior window — but that’s statistically rare and the error is bounded.
Compare fixed window, sliding window log and sliding window counter
| Fixed Window | Sliding Window Log | Sliding Window Counter | |
|---|---|---|---|
| Memory | O(1) | O(N requests) | O(1) |
| Accuracy | Boundary exploit | Exact | ~99% accurate |
| Implementation | Trivial | Moderate | Moderate |
| Redis structure | String | Sorted Set | String |
| Best for | Internal, low-stakes | Billing, quotas | Public APIs, high throughput |
The Boundary Exploit — Eliminated?
Not perfectly, but dramatically reduced. In a pure fixed window, you can burst 2× the limit across a boundary. With the sliding counter, the weighted formula ensures past requests keep contributing even after the window flips, so a burst near a boundary is partially penalised. The only residual error is the uniform-distribution assumption about the previous window.
Decision Guide
Need to allow legitimate bursts (mobile clients, retries)?
└── Token Bucket

Need perfectly smooth outbound traffic (payments, SMS, external API calls)?
└── Leaky Bucket

Simplest possible implementation, internal service, low stakes?
└── Fixed Window Counter

Exact accounting required (billing, quota enforcement, SLAs)?
└── Sliding Window Log

Everything else — public API, high throughput, good enough accuracy?
└── Sliding Window Counter ← default choice for most systemsUse cases
| Scenario | Algorithm | Reason |
|---|---|---|
| Public REST API (general purpose) | Sliding Window Counter | O(1) memory, ~99% accurate, no boundary exploit |
| Billing/quota enforcement | Sliding Window Log | Exact counts, no approximation acceptable |
| External API calls (SMS, email, payment gateway) | Leaky Bucket | You need smooth outflow, not bursty requests |
| Mobile clients/retries with backoff | Token Bucket | Clients naturally burst; bucket absorbs it gracefully |
| Login / OTP endpoints | Sliding Window Counter | Approximate is fine, simple to ops, low memory |
| Internal microservice calls | Fixed Window Counter | Low stakes, trivial to implement, fast |
| Per-user download/bandwidth throttle | Token Bucket | Burst for small files, sustained limit for large ones |
| Webhooks/event delivery | Leaky Bucket | Downstream expects steady rate, not spikes |
| DDoS / abuse protection at edge | Sliding Window Counter | Needs to run at scale across millions of IPs cheaply |
| SLA-bound API tiers (free / pro/enterprise) | Token Bucket | Capacity and refill rate map directly to tier limits |
| Admin/management APIs | Fixed Window Counter | Low traffic, simplicity beats precision |
| Financial transactions | Sliding Window Log | Exact audit trail, correctness over performance |
| CI/CD pipeline triggers | Fixed Window Counter | Bursty by nature but low volume, simplicity wins |
| WebSocket / streaming connections | Token Bucket | Connection bursts on reconnect, sustained flow after |
| Search/autocomplete endpoints | Sliding Window Counter | High QPS, O(1) memory critical, slight inaccuracy fine |
Rate limiting in the distributed system
In simple systems, all requests come from the same rate limiter.
In a distributed environment with multiple data centres. The load balancer is required to manage requests across multiple servers and multiple data centres. Hence, we need multiple implementations of the rate limiter, as every data centre has its own implementation of this middleware.
We must maintain a common cache to maintain state. We need one shared cache across a distributed network.
Conclusion
Rate limiting is a vital technique for managing traffic and ensuring the stability, performance, and security of web services. By understanding the various methods and best practices for rate limiting, you can effectively control the flow of requests to your server and provide a better experience for all users.
Incorporating rate limiting into your system is not just about preventing abuse; it’s about creating a balanced and fair environment that can handle the demands of modern web traffic. Whether you are a developer, system administrator, or security professional, mastering the concept of rate limiting is essential for the robust management of your online services.
